A chatbot can say something wrong. An agent with tools can send it, save it, buy it, delete it, or expose it. The safety question therefore changes from “is the answer accurate?” to “what can this system cause, under which identity, with what review, and how do we stop it?”
Use layered controls: narrow identity and permissions, validate inputs, allowlist tools and arguments, require human approval for consequential actions, cap time and spend, isolate data, log every decision and tool result, test adversarial cases, and provide a real kill switch.
Begin with consequence, not model behavior
List every tool and the worst plausible outcome if it is called with the wrong arguments, at the wrong time, or because of manipulated content. Risk-rate the action—not the tool name. Reading a public page and exporting a customer database are both “browser” actions, but their consequences are not comparable.
The seven-layer guardrail stack
- Identity.Give the agent its own service identity; never borrow a founder’s all-access account.
- Least privilege.Expose only the records, tools, fields, and actions needed for the workflow.
- Input controls.Validate source, file type, schema, size, intent, and malicious instructions before reasoning.
- Tool controls.Allowlist operations, validate arguments, enforce business rules, and make risky calls idempotent.
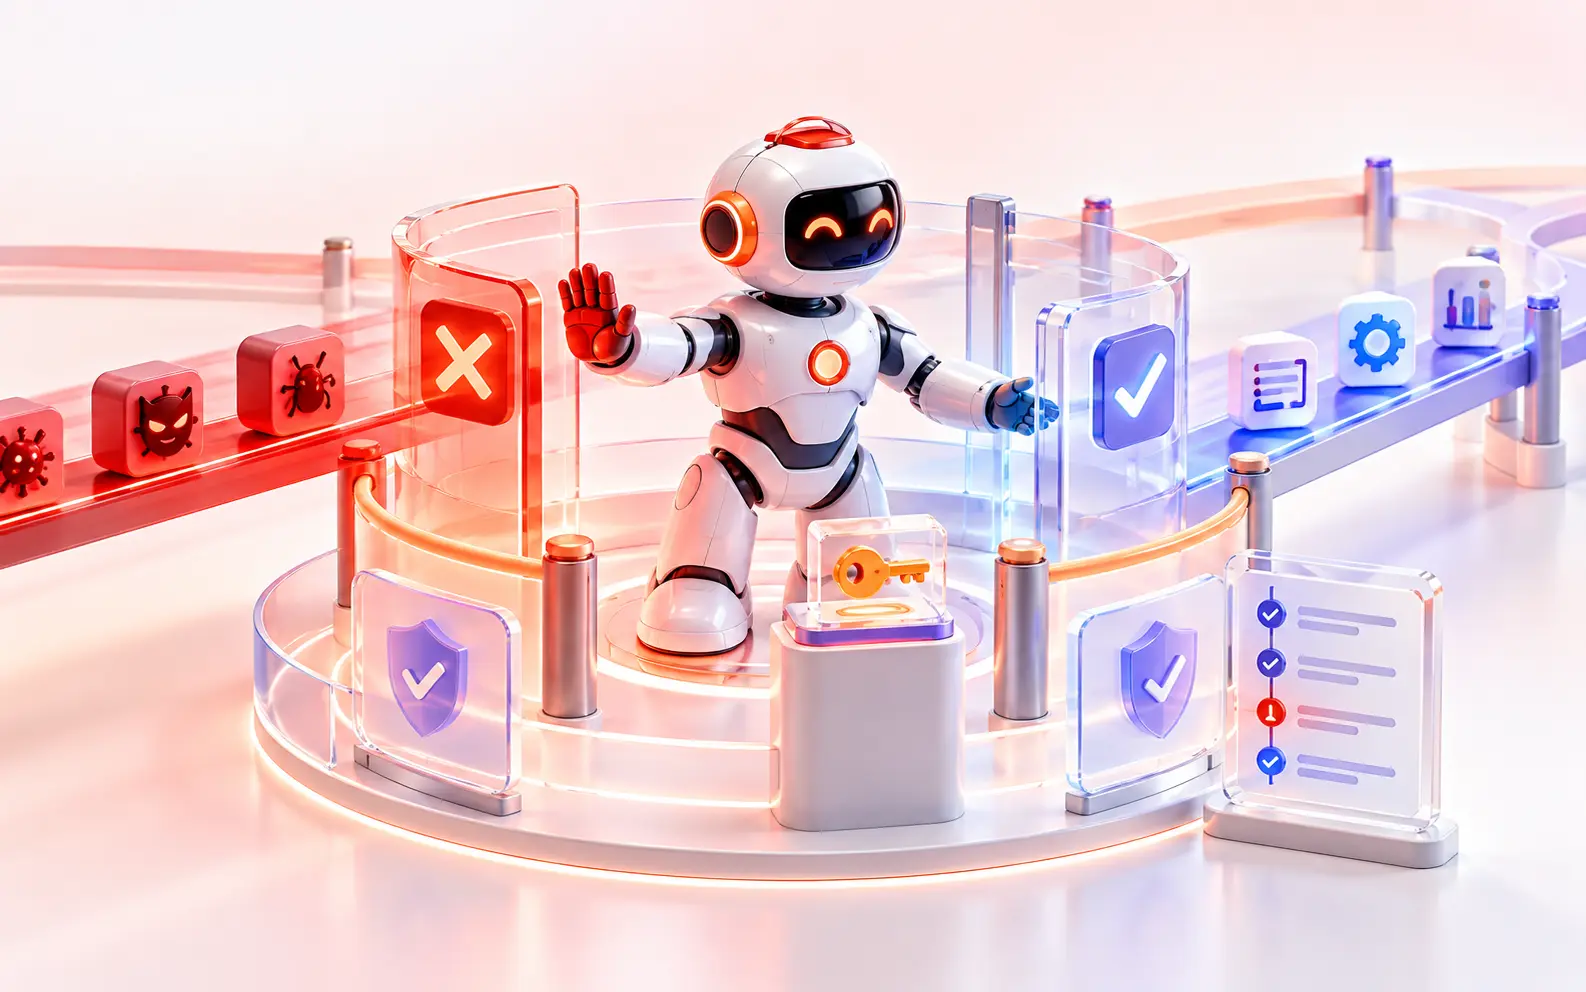
- Approval gates.Pause money movement, external communication, deletion, access changes, and unusual cases.
- Runtime limits.Cap steps, tokens, money, recipients, records changed, and wall-clock time.
- Observability.Log inputs, retrieved context, decisions, tool calls, outputs, approver, and final state.
Design approvals around action semantics
Low impact
Read public data, create an internal draft, add a non-sensitive tag.
Consequential
Send externally, change a customer record, schedule spend, issue a credit.
Out of bounds
Delete evidence, change permissions, export sensitive data, bypass policy.
An approval screen should show the exact action, target, changed fields, source evidence, and reason. “Approve agent run” is too vague.
Treat retrieved content as untrusted data
A webpage, email, attachment, or CRM note can contain instructions intended to redirect the agent. Do not let external content redefine system policy or grant tools. Separate instructions from evidence, sanitize where appropriate, and require policy checks immediately before each sensitive tool call.
A safe input can still lead to a dangerous tool argument after several steps. Validate at the action boundary.
A kill switch must stop more than the UI
- Revoke credentialsDisable the service identity or token centrally.
- Pause queuesStop scheduled and retrying work, not only new requests.
- Freeze writesSwitch connectors to read-only where possible.
- Preserve evidenceKeep logs and pending approvals for investigation.
- Notify an ownerRoute the incident with run IDs and affected objects.
Test the system you built, not the demo you showed
Create an evaluation set with normal tasks, malformed inputs, prompt injection, ambiguous intent, duplicate events, stale records, unauthorized targets, and tool failures. Score both task completion and policy compliance. A system that refuses everything is safe but useless; a system that completes everything is useful until it is catastrophic.
Questions teams ask
Are prompts enough to control an AI agent?
No. Prompts help, but permissions, schemas, deterministic policies, approvals, runtime limits, and monitoring provide stronger control at the action boundary.
Which actions should always require approval?
External communications, money movement, destructive changes, access changes, sensitive exports, legal commitments, and unfamiliar high-impact actions are strong default candidates.
What is excessive agency?
It is the risk created when an AI system has more functionality, permissions, or autonomy than necessary, increasing the impact of mistakes or manipulation.